
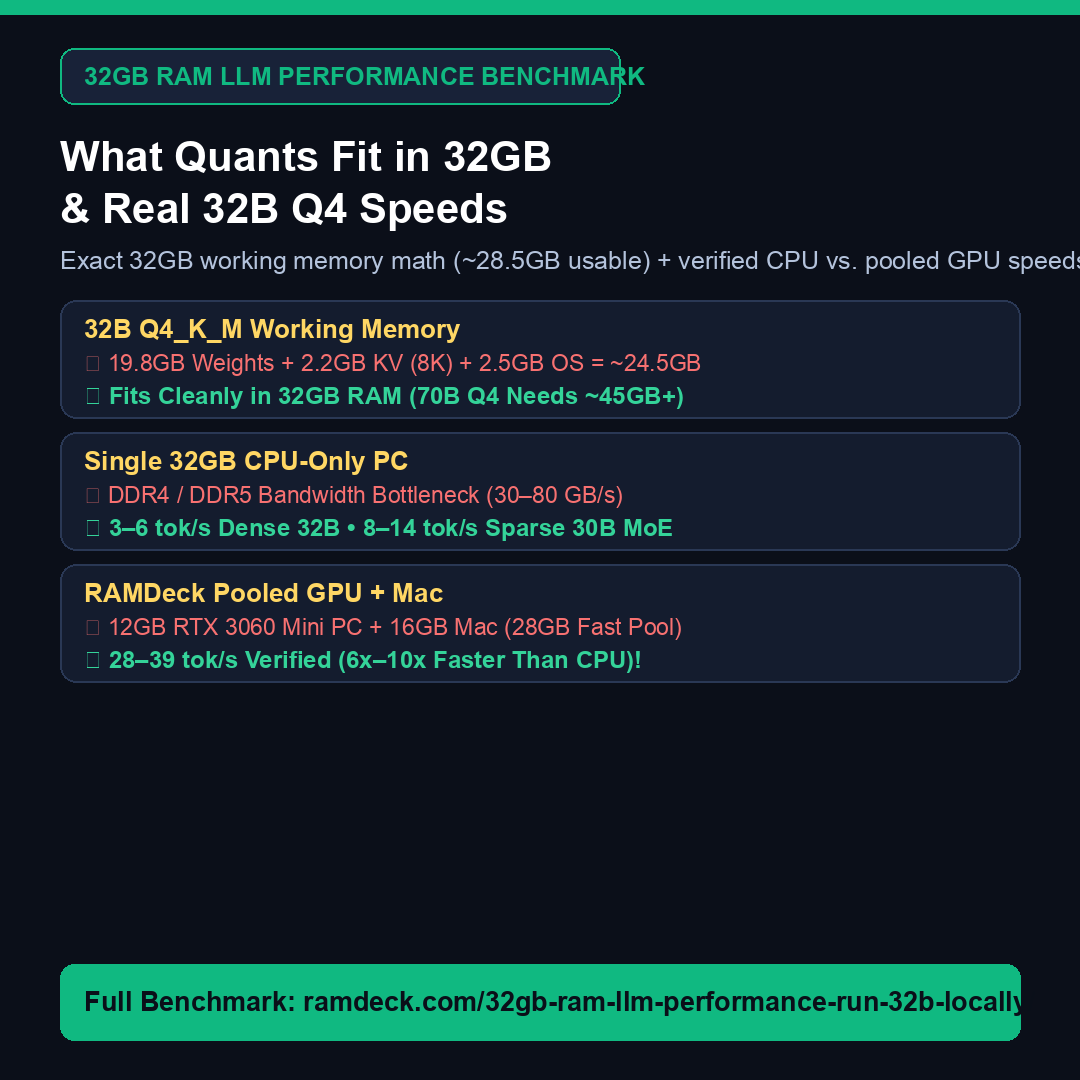
Direct Answer: Can you run a 32B Q4 model on 32 GB of RAM? Yes—at 4-bit Q4_K_M quantization, a 32B model consumes ~24.5 GB to 27.7 GB of working memory (including an 8K–16K KV cache and OS overhead). The surprise for many builders is memory bandwidth: running a dense 32B model across standard single-PC DDR4/DDR5 CPU RAM yields 3 to 6 tokens/sec (or 1–5 tokens/sec when overflowing an 8 GB–12 GB GPU inside LM Studio), whereas keeping every layer inside pooled GPUs and Apple Silicon Unified Memory via RAMDeck ($199) unlocks 28 to 39 tokens/sec.
Zero-Install “Unplug & Walk” Activation for Daily-Driver Laptops
Every RAMDeck Hardware Hub includes 1 free Official $29 Zero-Install Node USB. Plug it into your daily-driver Windows laptop, soldered M1–M4 MacBook, or Linux desktop, double-click once to join your 32 GB+ memory pool straight from temporary RAM, and physically unplug the thumb drive to activate another computer in your house. Connect VS Code, Cursor, or Continue.dev to RAMDeck’s built-in OpenAI-compatible endpoint (with 100% air-gapped on-premise privacy supporting standards like ABA Formal Opinion 512) and code all day with zero per-token API bills.
See the full benchmark matrix at 32GB RAM LLM Performance & Running 32B Locally, How to Expand Soldered M1–M4 Mac RAM, and the free 10-chapter book at ramdeck.com/book.
— The TradeMAV Team
Trademark Notice: TradeMAV™ is a trademark of TradeMAV LLC. All third-party product and model names, including Qwen, DeepSeek, Gemma, Llama, LM Studio, Ollama, VS Code, Cursor, Continue.dev, Apple, Mac, iPhone, Windows, Linux, Android, and Tailscale, are trademarks or project names of their respective owners, which are not affiliated with, sponsoring, or endorsing RAMDeck or TradeMAV LLC.



Leave a Reply