
Direct Answer: Running modern 30B, 70B, or 120B local LLMs on Linux (Ubuntu, Debian, Fedora, Mint, or headless servers) usually forces engineers to spend hours compiling source code with custom build flags, managing complex service configurations, or troubleshooting package dependencies. With RAMDeck’s native Linux support, users install a lightweight pre-built .deb package or standalone bundle that launches a systemd background daemon and provides a clean browser-based Web Control Panel on port 50051 (completely bypassing desktop UI crashes)—allowing Linux homelabs to auto-discover and pool memory with Windows PCs, Macs, and phones in 60 seconds.
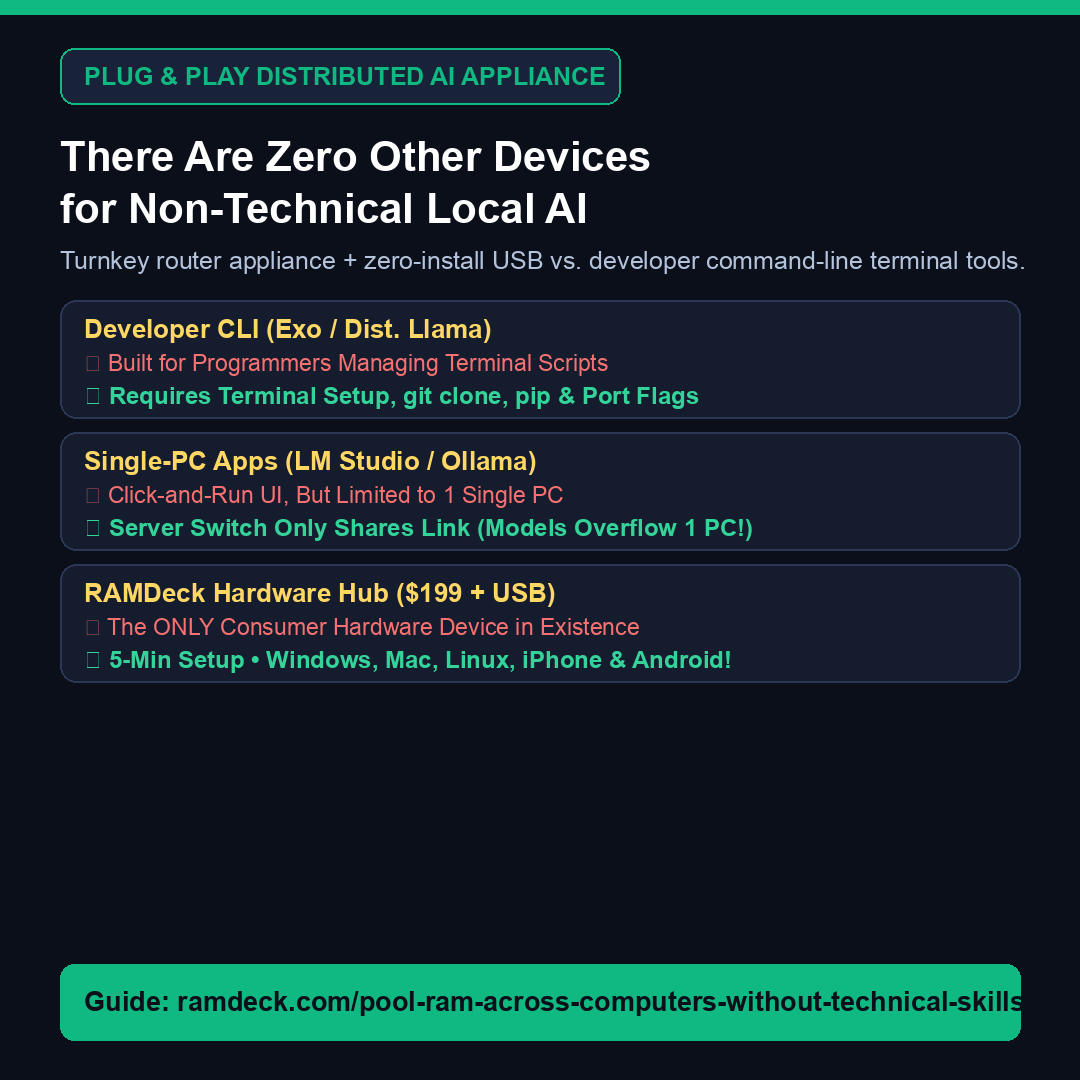
Hardware-Priority Layer Allocation Across Mixed Operating Systems
Modern homes and labs rarely have identical server hardware. RAMDeck pools whatever you have sitting on your local network:
- Linux Ubuntu Desktop / Mini PC: Contributes 28 GB of fast DDR5 system memory as a high-capacity worker.
- Windows RTX 3060 PC: Computes initial dense layers at lightning speed inside 12 GB of CUDA VRAM.
- Apple Silicon Mac: Contributes 16 GB of unified memory with high-bandwidth Metal 3 GPU shaders.
Combined, this patchwork creates a 56 GB+ cluster running 30B models at 38–39 tokens/sec and 70B models smoothly. Read the full step-by-step tutorial at How to Run an LLM on Linux, PC & Mac and explore the free 10-chapter book at ramdeck.com/book.
— The TradeMAV Team
Trademark Notice: TradeMAV™ is a trademark of TradeMAV LLC. All third-party product and model names, including Qwen, DeepSeek, Gemma, Llama, LM Studio, Ollama, VS Code, Cursor, Ubuntu, Linux, Apple, Mac, Windows, and Tailscale, are trademarks or project names of their respective owners, which are not affiliated with, sponsoring, or endorsing RAMDeck or TradeMAV LLC.



Leave a Reply